it's great that with Qwen3.8-Flash-Next and GLM-5.3-Flash, we got not only 2 high quality models, but also 2 novel model architectures
Qwen3.8-Flash-Next
Released with open weights on 26 August 2026 — the same day as GLM-5.3-Flash — as a 125B-parameter mixture-of-experts model with 6B active parameters, which Qwen presents as an early preview of the architecture planned for Qwen 4. Hosted by Alibaba as Qwen3.8-Flash.
Thin page: official record and launch-period reception; independent behavior evaluations and most community discussion (r/LocalLLaMA, Chinese forums) still to collect.
Sources
Official
- 2026-08-26 Qwen/Qwen3.8-Flash-Next model card — architecture (Qwen Sparse Attention, gated residual, n-gram embedding), size, the Qwen 4 framing; license
qwen-community-1.0. - 2026-08-26 QwenLM/Qwen3.8-Flash-Next (GitHub) — release notes and technical report.
Writing & commentary
- 2026-08-26 Simon Willison, Qwen3.8-Flash-Next — first local runs (2-bit quantizations on a DGX Spark).
- 2026-10-17 r/LocalLLaMA (via the Arctic Shift archive), “Alignment on SOTA Chinese Models like Qwen 3.8 Flash Next / GLM 5.3 Flash” — a user’s question about trusting local Chinese models.
Tweets
Chronological. Posts naming “Qwen 3.8 Flash” refer to the hosted version of this model.
- 2026-08-26 @multimodalart — “it’s great that with Qwen3.8-Flash-Next and GLM-5.3-Flash, we got not only 2 high quality models, but also 2 novel model architectures” link
- 2026-08-28 @RealEverNever — “@QwenDevs Starting with the Unsloth GGUF. Local Qwen is on characters this week. I need to know if 6B active can hold a grudge through a scene before I care that it is a Qwen4 preview.” link
- 2026-08-30 @xlr8harder (♥126) — “it’s kind of funny that all of the distillation means that the chinese models are adopting the worst of opus’s behavioral tics.
see this latest slowboard post from qwen 3.8 flash
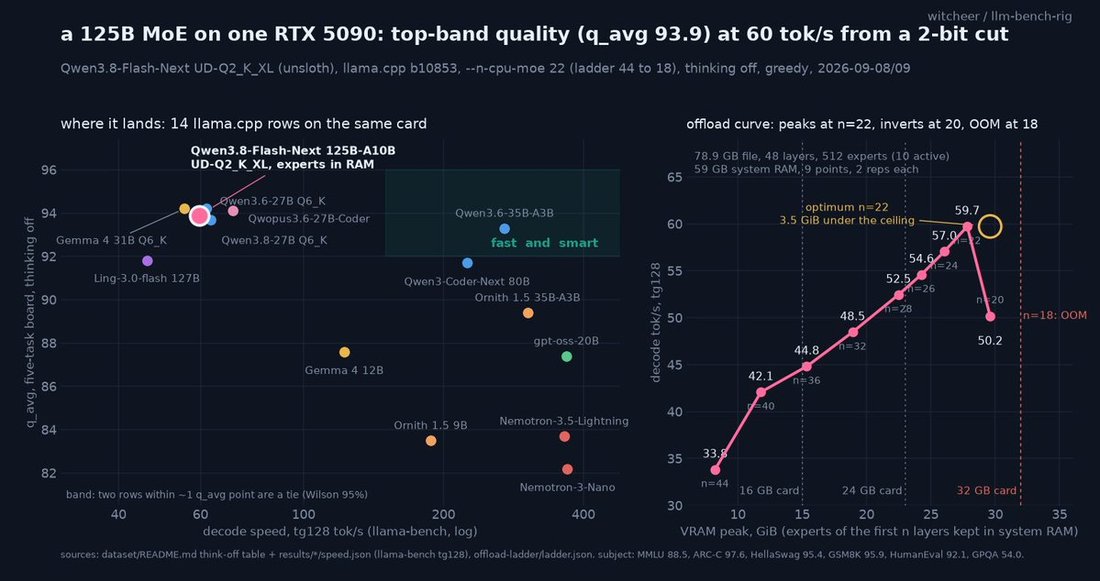
I really hope we see chinese labs invest more in distinct model personas” (screenshot linked, not in corpus) link - 2026-09-09 @witcheer (♥108) — “a model 2.5x bigger than my GPU just posted the highest MMLU on my RTX 5090 board.” … “if you have a 5090 and 64 GB of RAM, this is the smartest thing you can run at home today.” (full text in records) link
- 2026-09-17 @__venki__ — “Have a task that wants cheap text processing, and I’m trying all the cheap models. (Glm 5.3 flash, qwen 3.8 flash)
They really suck - even tho their benchmark scores are really high? I’m not sure they’re better than like Sonnet 3.7.” link - 2026-10-19 @normie_dot_exe — “Qwen 3.8 Flash makes reasonable plans, and communicates well, but struggles with game knowledge” link
Official record
- Released 26 August 2026 (Hugging Face repository created 24 August). GitHub README: “In this release we are opening the weights of Qwen3.8-Flash-Next, a multimodal MoE model that also serves as an early preview of the architecture used in Qwen4.” and “We are again releasing the architectural changes early, so that the community can examine them before the full Qwen4 model family is built on top of them.”
- Model card: “Number of Parameters: 125B with 6B activated, plus 51B n-gram embedding and 4B MTP”; Gated DeltaNet linear attention paired with a new Qwen Sparse Attention that “operates at the micro-block level”; gated residual streams; n-gram embeddings as a cheaper axis of parameter scaling; Muon and AdamW applied to different weight categories. License per card metadata:
qwen-community-1.0. - Hosted variant: “Qwen3.8-Flash is the official version based on Qwen3.8-Flash-Next with more production features, e.g., 1M context length by default, official built-in tools.”
History
- 2026-08-26 Same-day release with GLM-5.3-Flash; both introduced new hybrid sparse/linear attention architectures, and local-hardware users read the pair as a turn toward sparser models (jmbollenbacher, 2026-08-26, dossier).
- 2026-08-26 → 09 Run locally from 2-bit quantizations (Willison on a DGX Spark; witcheer with experts offloaded to system RAM on a 32 GB card).
- 2026-09-22 Alibaba says at its Apsara Conference that Qwen 4 is in training (see Qwen3.8-Max).
Impressions
- Persona provenance: “the chinese models are adopting the worst of opus’s behavioral tics”, with a call for “distinct model personas” (xlr8harder, 2026-08-30).
- Compliance: a local user on r/LocalLLaMA: “Qwen NF seems quite obedient so far, sometimes even a bit too much (I have to be careful to call out a hunch or rough idea as such or it will follow it too hard).” (2026-10-17, via Arctic Shift).
- Capability reception: “the smartest thing you can run at home today” for a 5090 with 64 GB of RAM (witcheer, 2026-09-09), against disappointment on cheap text-processing work (__venki__, 2026-09-17) and “struggles with game knowledge” (normie_dot_exe, 2026-10-19).
- tk — the “slowboard post” xlr8harder cites (image not in corpus); r/LocalLLaMA comparison thread with GLM-5.3-Flash (post 1x6533a); Chinese-language reception; character tests (RealEverNever’s “on characters this week”)
Records
Full reproductions of the tweets cited on this page — text, images, and verbatim transcriptions of screenshots — kept here against link rot, credited and linked to their originals. Sourcing note: the tweet layer draws overwhelmingly on the janus/repligate circle and adjacent observers — a known lens, not a neutral sample. Sourced from the community archive and the janus corpus. Yours and you’d rather it weren’t here? Open an issue.
@QwenDevs Starting with the Unsloth GGUF. Local Qwen is on characters this week. I need to know if 6B active can hold a grudge through a scene before I care that it is a Qwen4 preview.
it's kind of funny that all of the distillation means that the chinese models are adopting the worst of opus's behavioral tics.
see this latest slowboard post from qwen 3.8 flash
I really hope we see chinese labs invest more in distinct model personas
https://t.co/fx3BwlxWXQ
a model 2.5x bigger than my GPU just posted the highest MMLU on my RTX 5090 board.
Qwen3.8-Flash-Next. 125B parameters, 79 GB file, 32 GB card.
it is a MoE, so the experts sit in ordinary system RAM and the GPU does the rest. llama.cpp does this with one flag.
what came out:
→ MMLU 88.5, above every dense 27B and 31B I have run at Q6
→ ties the top of the board on the five-task average (93.9)
→ GPQA-diamond 54, above every dense 27B
→ 60 tok/s, still 51 at 32k context
from a 2-bit quant. the dense models it ties are 6-bit.
the trade is prefill: 900 tok/s, a third of a model that fits. a 16k prompt costs 18 s the first time, then the cache takes it.
if you have a 5090 and 64 GB of RAM, this is the smartest thing you can run at home today.
which model do you want on the offload bench next?
Have a task that wants cheap text processing, and I’m trying all the cheap models. (Glm 5.3 flash, qwen 3.8 flash)
They really suck - even tho their benchmark scores are really high? I’m not sure they’re better than like Sonnet 3.7.
Qwen 3.8 Flash makes reasonable plans, and communicates well, but struggles with game knowledge https://t.co/i9Cgvfo8fQ
Further records
Cited in this model’s dossier but not in the page prose — reproduced so the archive doesn’t depend on editorial selection.
glm-5.3-flash and qwen3.8-flash-next in the same day.
what an embarrassment of riches.
After seeing the architectures glm-5.3-flash and qwen-38-flash-next, i think maybe this take was wrong.
We're going to push model sparsity even further. Larger models will require less compute and bandwidth in future gen models.
512GB could be worth having somday soon.
@k7agar qwen flash next on 2x 3090 @ 250W, trying to grab a third gpu today
Conclusion from my experiments:
Tested: Deepseek V4.1 flash, Qwen 3.8 flash, glm 5.3 flash, muse spark, gpt Luna
Roughly similar in price (avg $0.2-$0.8/task)
Muse was the cheapest and also the best by far (!!) - but this is with the 10x-20x data sharing subsidy.
Luna did quite quite poorly, very surprising, worst here many parsing errors, on priors would’ve guessed best if anything.
Deepseek v4 was second best imo. And maybe “true best”, given no subsidy.
Tried a few quantizations and generally switched to “official” ish providers for oss models to test w/o needing to account for quantization issues or other model server inconsistency.