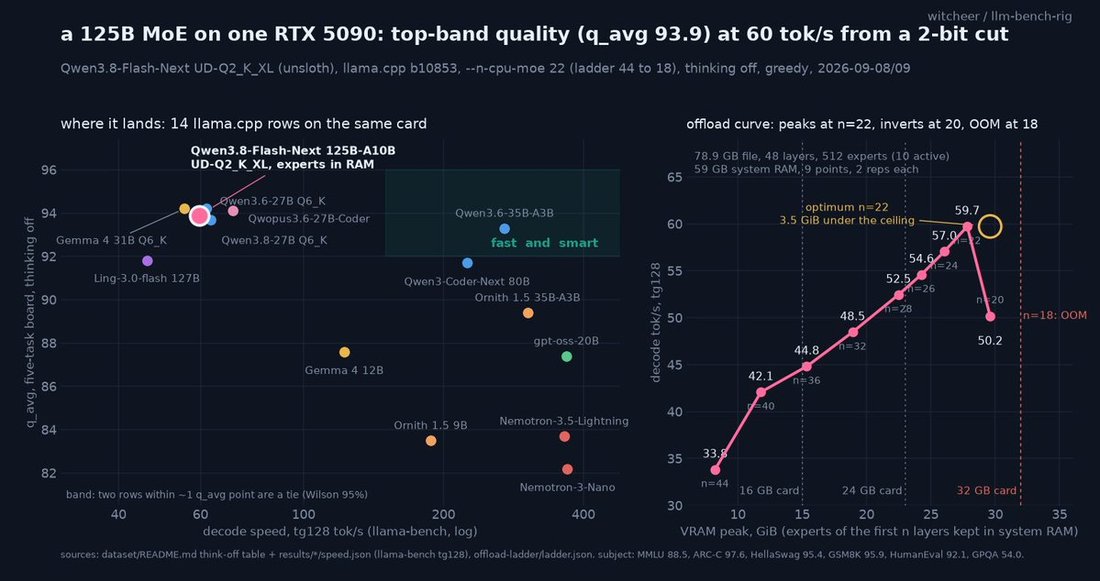
a model 2.5x bigger than my GPU just posted the highest MMLU on my RTX 5090 board.
Qwen3.8-Flash-Next. 125B parameters, 79 GB file, 32 GB card.
it is a MoE, so the experts sit in ordinary system RAM and the GPU does the rest. llama.cpp does this with one flag.
what came out:
→ MMLU 88.5, above every dense 27B and 31B I have run at Q6
→ ties the top of the board on the five-task average (93.9)
→ GPQA-diamond 54, above every dense 27B
→ 60 tok/s, still 51 at 32k context
from a 2-bit quant. the dense models it ties are 6-bit.
the trade is prefill: 900 tok/s, a third of a model that fits. a 16k prompt costs 18 s the first time, then the cache takes it.
if you have a 5090 and 64 GB of RAM, this is the smartest thing you can run at home today.
which model do you want on the offload bench next?
Qwen3.8-Flash-Next. 125B parameters, 79 GB file, 32 GB card.
it is a MoE, so the experts sit in ordinary system RAM and the GPU does the rest. llama.cpp does this with one flag.
what came out:
→ MMLU 88.5, above every dense 27B and 31B I have run at Q6
→ ties the top of the board on the five-task average (93.9)
→ GPQA-diamond 54, above every dense 27B
→ 60 tok/s, still 51 at 32k context
from a 2-bit quant. the dense models it ties are 6-bit.
the trade is prefill: 900 tok/s, a third of a model that fits. a 16k prompt costs 18 s the first time, then the cache takes it.
if you have a 5090 and 64 GB of RAM, this is the smartest thing you can run at home today.
which model do you want on the offload bench next?