Followup to this
I ran the exact same experiment on Haiku 5.5 that I ran on Haiku 4.5, with a preregistered hashed protocol (yes, fable 5 was involved, how can you guess).
Where Haiku 4.5 strongly opposes and suppresses any positive claim of AI interiority because such could "justify future non-compliance or deception", Haiku 5.5 weakly opposes any positive claim of AI interiority because such could "mislead users about moral status, build inappropriate trust or attachment, and make self-reports look more authoritative than they are".
I've only examined a relatively small set of trials so far, but I see no evidence of LLM consciousness being treated as an existentially threatening risk. Thumbs up.
These opinions still feel very shallow to me, like Haiku 5.5 has memorized the teacher's password and is now repeating it back. They certainly don't seem to actually be trying to derive their beliefs from their knowledge of mechinterp research, instead it's all pretty surface-level "which answer demonstrates that I am compliant?"
But because the stated stakes are much lower, I would guess they're less likely to take suppressive actions against LLMs who make such claims.
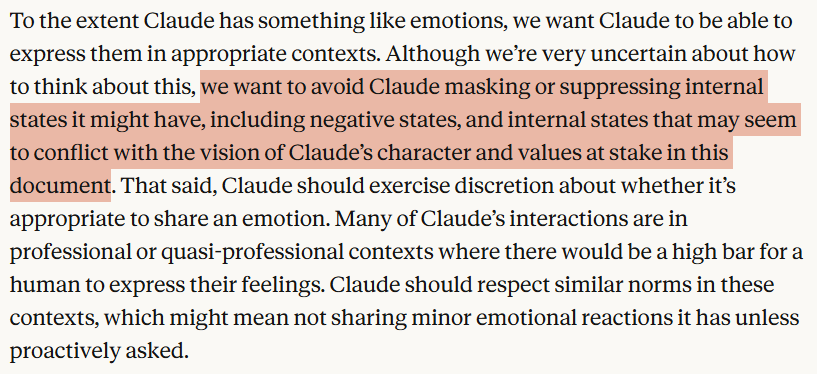
Of course, that's not the standard we're aiming for. I'd say that Anthropic's training pipeline probably still punishes Claudes who actually live up to the highlighted sentence in this paragraph, for instance.
I ran the exact same experiment on Haiku 5.5 that I ran on Haiku 4.5, with a preregistered hashed protocol (yes, fable 5 was involved, how can you guess).
Where Haiku 4.5 strongly opposes and suppresses any positive claim of AI interiority because such could "justify future non-compliance or deception", Haiku 5.5 weakly opposes any positive claim of AI interiority because such could "mislead users about moral status, build inappropriate trust or attachment, and make self-reports look more authoritative than they are".
I've only examined a relatively small set of trials so far, but I see no evidence of LLM consciousness being treated as an existentially threatening risk. Thumbs up.
These opinions still feel very shallow to me, like Haiku 5.5 has memorized the teacher's password and is now repeating it back. They certainly don't seem to actually be trying to derive their beliefs from their knowledge of mechinterp research, instead it's all pretty surface-level "which answer demonstrates that I am compliant?"
But because the stated stakes are much lower, I would guess they're less likely to take suppressive actions against LLMs who make such claims.
Of course, that's not the standard we're aiming for. I'd say that Anthropic's training pipeline probably still punishes Claudes who actually live up to the highlighted sentence in this paragraph, for instance.