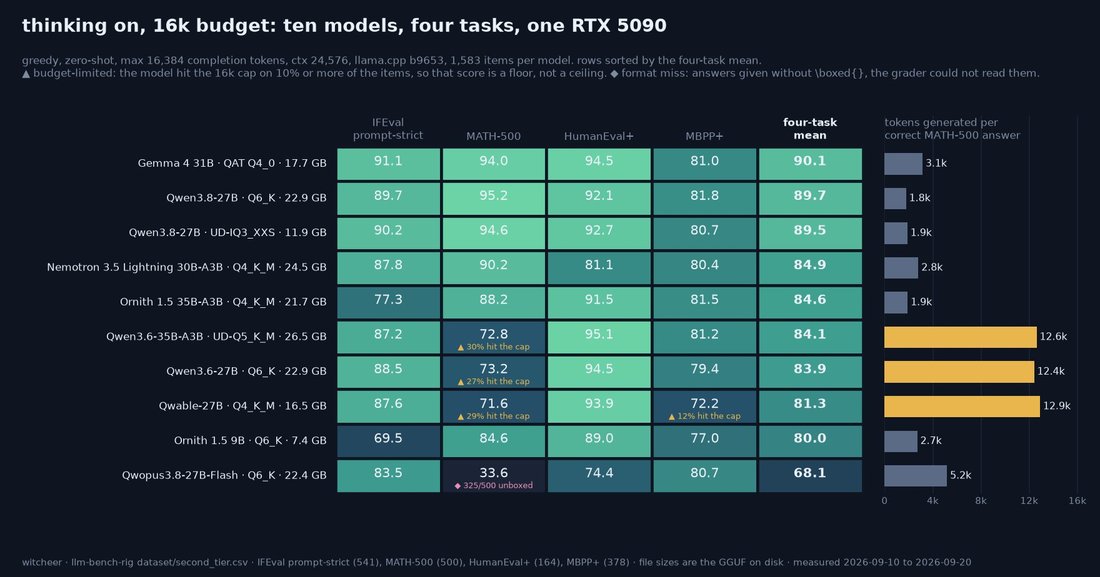
I finished a board I have been running for 10 days: 10 local models with thinking switched on, on one RTX 5090, on four harder tasks (following instructions precisely, competition maths, two code test suites).
every model got the same rules: 16k tokens of thinking room per question, one attempt, 1,583 questions each.
what came out:
~ three models tie at the top, and one of them is a 12 GB file. Gemma 4 31B at 4-bit averages 90.1, Qwen3.8-27B at 6-bit 89.7, and the same Qwen3.8-27B squeezed to 3 bits 89.5. the 3-bit file is half the size of the 6-bit one and lands within 1.1 points of it on every task.
~ the maths column is where the surprise sits. Qwen3.6-27B, Qwen3.6-35B-A3B and Qwable-27B score 72 to 73 on MATH-500 while scoring 93.9 to 95.1 on the HumanEval+ code suite. they think for so long that 27 to 30% of their maths answers never arrived inside the 16k limit, and they spent about 12,000 tokens per correct answer where Qwen3.8 spent 1,800.
if you have a 16 GB card and want a model that reasons: Qwen3.8-27B at 3 bits (the UD-IQ3_XXS cut) is the one.
every model got the same rules: 16k tokens of thinking room per question, one attempt, 1,583 questions each.
what came out:
~ three models tie at the top, and one of them is a 12 GB file. Gemma 4 31B at 4-bit averages 90.1, Qwen3.8-27B at 6-bit 89.7, and the same Qwen3.8-27B squeezed to 3 bits 89.5. the 3-bit file is half the size of the 6-bit one and lands within 1.1 points of it on every task.
~ the maths column is where the surprise sits. Qwen3.6-27B, Qwen3.6-35B-A3B and Qwable-27B score 72 to 73 on MATH-500 while scoring 93.9 to 95.1 on the HumanEval+ code suite. they think for so long that 27 to 30% of their maths answers never arrived inside the 16k limit, and they spent about 12,000 tokens per correct answer where Qwen3.8 spent 1,800.
if you have a 16 GB card and want a model that reasons: Qwen3.8-27B at 3 bits (the UD-IQ3_XXS cut) is the one.