the loudest specific complaint in Alex Cheema's thread on why people don't run local models was prefill: a coding agent hands the model a long prompt and you wait for the first token, every request.
two llama-server flags remove most of that wait, and both are free. I measured them on the model my always-on box serves every day.
Qwen3.8-27B Q6_K, llama.cpp, one RTX 5090, batch 1, 304 requests, one variable at a time.
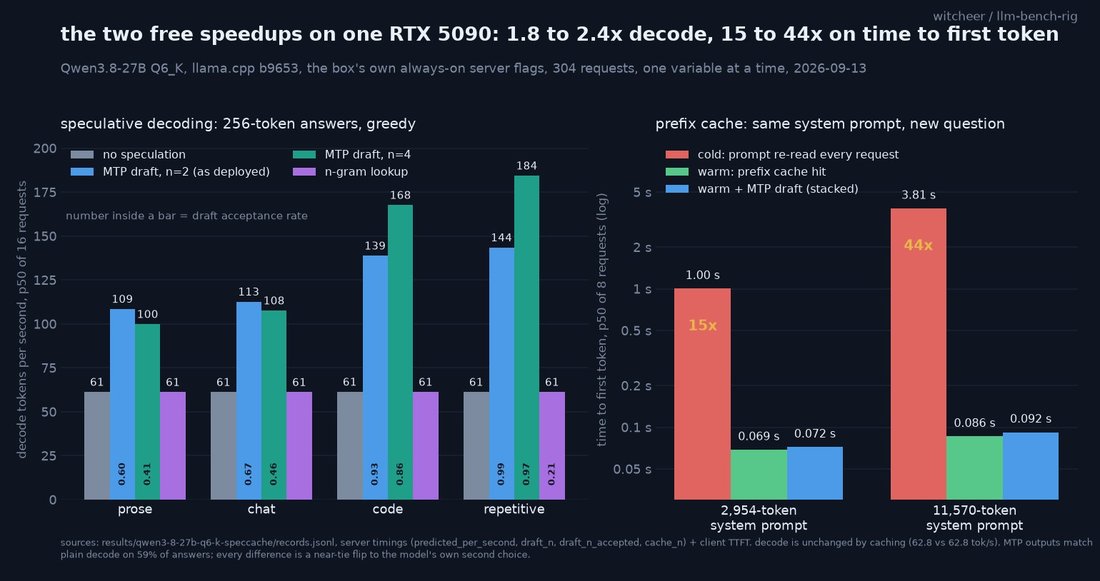
prompt caching, same system prompt, new question:
- 2,954-token prompt: 1.004 s -> 0.069 s to first token
- 11,570-token prompt: 3.814 s -> 0.086 s
decode speed untouched.
speculative decoding (the model's own MTP draft head, n=2):
- prose 61 -> 109 tok/s
- chat 61 -> 113
- code 61 -> 139
- repetitive text 61 -> 144
cost: 9 ms on time to first token.
both on: a short answer to the 11.5k context goes 4.25 s -> 0.30 s.
two llama-server flags remove most of that wait, and both are free. I measured them on the model my always-on box serves every day.
Qwen3.8-27B Q6_K, llama.cpp, one RTX 5090, batch 1, 304 requests, one variable at a time.
prompt caching, same system prompt, new question:
- 2,954-token prompt: 1.004 s -> 0.069 s to first token
- 11,570-token prompt: 3.814 s -> 0.086 s
decode speed untouched.
speculative decoding (the model's own MTP draft head, n=2):
- prose 61 -> 109 tok/s
- chat 61 -> 113
- code 61 -> 139
- repetitive text 61 -> 144
cost: 9 ms on time to first token.
both on: a short answer to the 11.5k context goes 4.25 s -> 0.30 s.