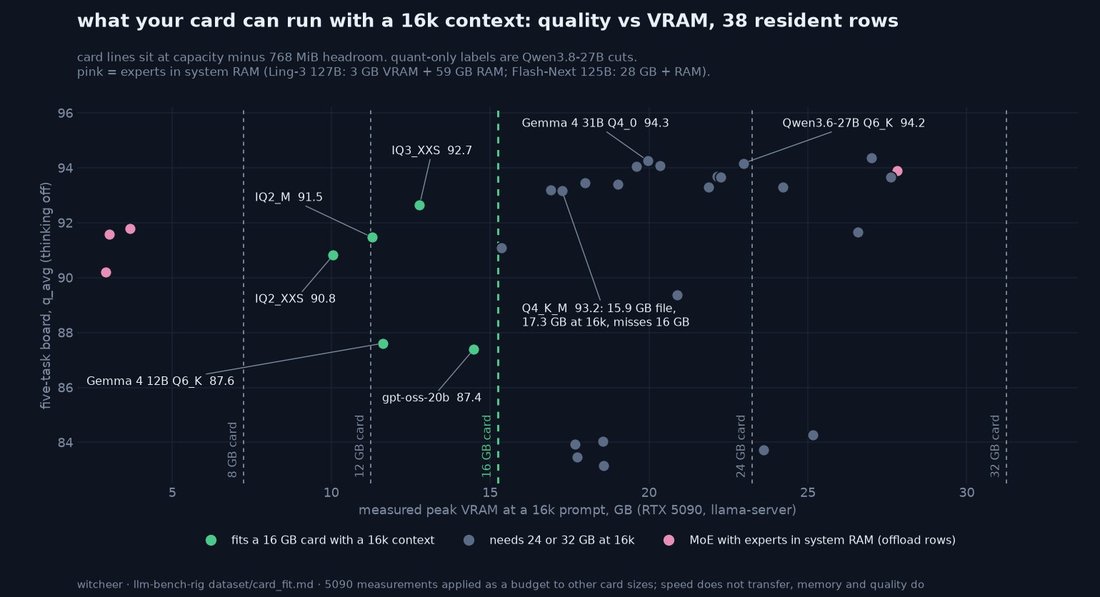
I turned every row on the RTX 5090 board into a fit table for 8, 12, 16, 24 and 32 GB cards: measured peak VRAM at a 16k prompt, plus 768 MiB of headroom, against the card size. 38 models and quants.
what a 16 GB card runs at 16k, by quality:
→ Qwen3.8-27B UD-IQ3_XXS: 92.7 board, 45.0 GPQA, 12.8 GB peak
→ Qwen3.8-27B UD-IQ2_M: 91.5, 11.3 GB
→ Qwen3.8-27B UD-IQ2_XXS: 90.8, 10.1 GB
→ Gemma 4 12B Q6_K: 87.6, 11.6 GB
→ gpt-oss-20b Q4_K_M: 87.4, 14.5 GB
the 27B at 3 bits beats every smaller model by 5 points. the cost shows on the harder set: GPQA-diamond 45.0 vs 49.0 for the 6-bit cut.
12 GB: the IQ2_XXS cut fits with a 16k context and still scores 90.8. 8 GB: nothing dense on this board fits resident.
Qwen3.8-27B Q4_K_M is a 15.9 GB file. it fits a 16 GB card. its 16k context does not (17.3 GB peak). shorten the context or use a q8 KV cache, not q4, which costs 17 to 29% of decode speed on every model I measured.
what a 16 GB card runs at 16k, by quality:
→ Qwen3.8-27B UD-IQ3_XXS: 92.7 board, 45.0 GPQA, 12.8 GB peak
→ Qwen3.8-27B UD-IQ2_M: 91.5, 11.3 GB
→ Qwen3.8-27B UD-IQ2_XXS: 90.8, 10.1 GB
→ Gemma 4 12B Q6_K: 87.6, 11.6 GB
→ gpt-oss-20b Q4_K_M: 87.4, 14.5 GB
the 27B at 3 bits beats every smaller model by 5 points. the cost shows on the harder set: GPQA-diamond 45.0 vs 49.0 for the 6-bit cut.
12 GB: the IQ2_XXS cut fits with a 16k context and still scores 90.8. 8 GB: nothing dense on this board fits resident.
Qwen3.8-27B Q4_K_M is a 15.9 GB file. it fits a 16 GB card. its 16k context does not (17.3 GB peak). shorten the context or use a q8 KV cache, not q4, which costs 17 to 29% of decode speed on every model I measured.