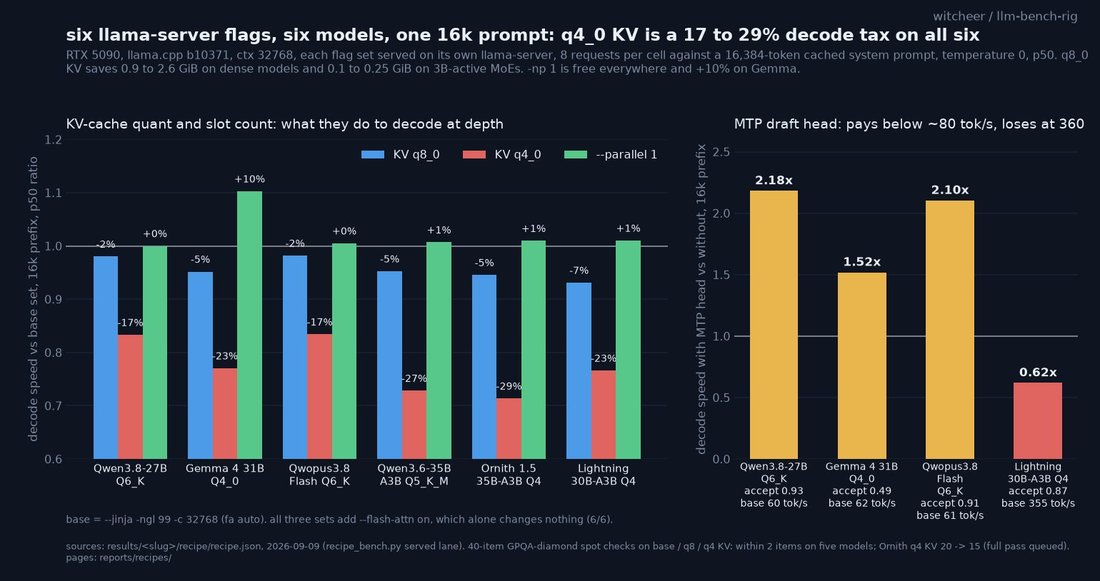
I measured the six llama-server flags everyone argues about, on a 16k prompt, on six models:
RTX 5090, Qwen3.8-27B, Gemma 4 31B, Qwen3.6-35B-A3B, Nemotron Lightning, Ornith 35B, Qwopus Flash.
→ --flash-attn on: changes nothing. auto already picks it.
→ --parallel 1: free. +10% decode at depth on Gemma, 2.3 GB back.
→ KV cache q8_0: a memory lever on dense models only (1 to 2.6 GB). on a 3B-active MoE it saves 0.1 GB and still costs 5 to 7%.
→ KV cache q4_0: the tax. -17%, -23%, -27%, -23%, -29%, -17% decode against a 16k context, six for six. quality did not move: a full 198-item GPQA run on Ornith put f16, q8 and q4 KV at 100, 100 and 98.
→ MTP draft head: 2.2x on Qwen3.8 (embedded head), 1.5x on Gemma (community head), 0.7x on Lightning. above ~300 tok/s the verification pass costs more than it saves.
the first token on a 16k prompt: 5 to 6 s cold, 0.1 to 0.4 s once cached.
RTX 5090, Qwen3.8-27B, Gemma 4 31B, Qwen3.6-35B-A3B, Nemotron Lightning, Ornith 35B, Qwopus Flash.
→ --flash-attn on: changes nothing. auto already picks it.
→ --parallel 1: free. +10% decode at depth on Gemma, 2.3 GB back.
→ KV cache q8_0: a memory lever on dense models only (1 to 2.6 GB). on a 3B-active MoE it saves 0.1 GB and still costs 5 to 7%.
→ KV cache q4_0: the tax. -17%, -23%, -27%, -23%, -29%, -17% decode against a 16k context, six for six. quality did not move: a full 198-item GPQA run on Ornith put f16, q8 and q4 KV at 100, 100 and 98.
→ MTP draft head: 2.2x on Qwen3.8 (embedded head), 1.5x on Gemma (community head), 0.7x on Lightning. above ~300 tok/s the verification pass costs more than it saves.
the first token on a 16k prompt: 5 to 6 s cold, 0.1 to 0.4 s once cached.