Ran some benchmarks testing out what you can get context and accuracy wise using a 16GB GPU.
Quick findings after several runs over several hours:
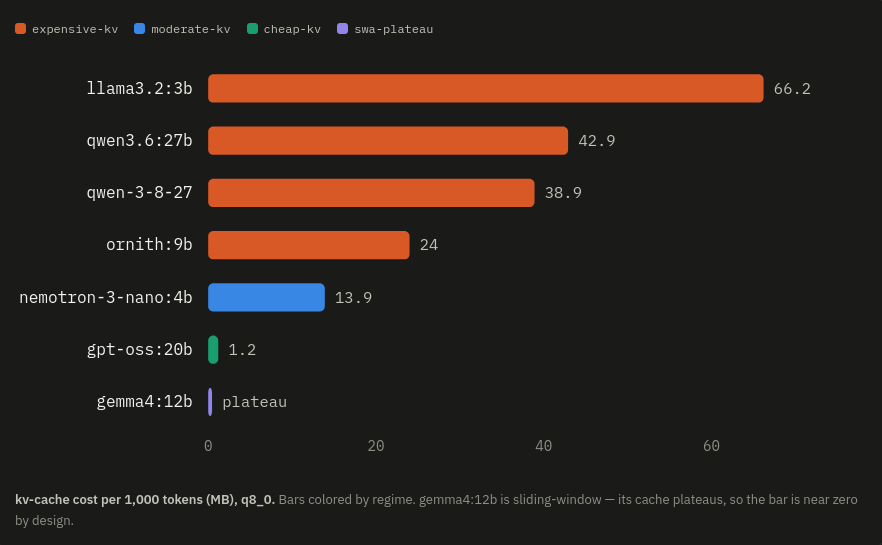
- Models vary massively in MB of memory / 1000 tokens
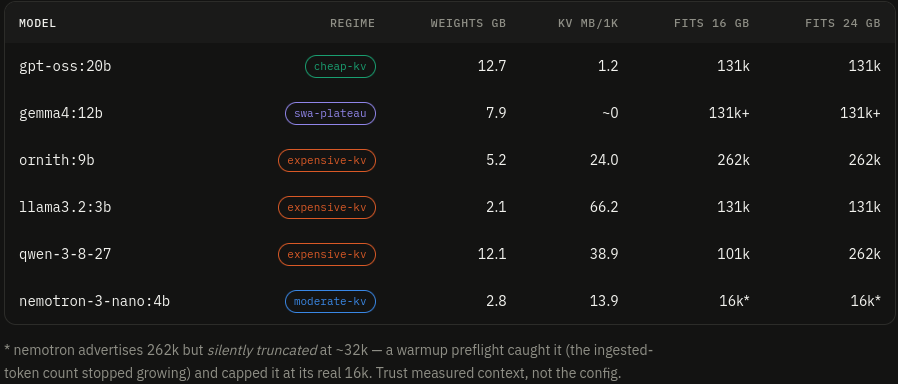
- For a given model, if it fits in VRAM to start with, odds are reasonable it can fit full context.
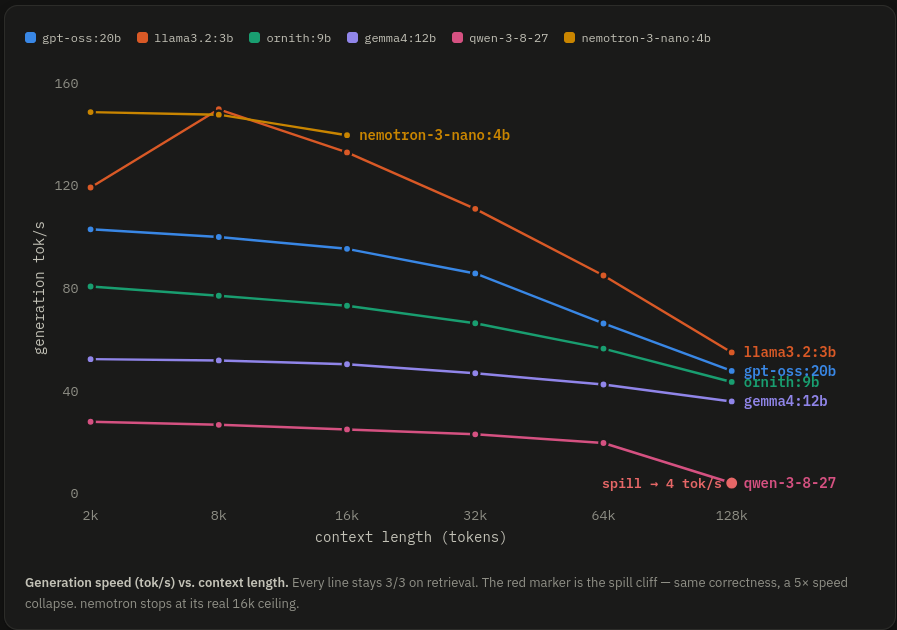
- Exceptions exist: Llama3.2 at 131k context would break out of an 8GB card. Qwen spills over 16GB at >65k.
- Spilling into system RAM is significantly slower but did not affect successful task outcome (needle hunting at various depths).
- Ingestion speed and first load is the bottleneck. Effective caching behavior may mitigate this for batched work.
Recommendations if you have a 16GB card:
For a model that reliably completes tasks, and fits a full 131k context into VRAM, gpt-oss threads the needle of speed and resource load.
For a model that reliably completes more complicated tasks slowly, a quantized qwen3.8:27b fitting into the profile will work if context length can be constrained to <65k, but it's slow.
More detailed report: https://t.co/9F3aXdZR1Y
Repo with results and code: https://t.co/llFCg1HgrU
Quick findings after several runs over several hours:
- Models vary massively in MB of memory / 1000 tokens
- For a given model, if it fits in VRAM to start with, odds are reasonable it can fit full context.
- Exceptions exist: Llama3.2 at 131k context would break out of an 8GB card. Qwen spills over 16GB at >65k.
- Spilling into system RAM is significantly slower but did not affect successful task outcome (needle hunting at various depths).
- Ingestion speed and first load is the bottleneck. Effective caching behavior may mitigate this for batched work.
Recommendations if you have a 16GB card:
For a model that reliably completes tasks, and fits a full 131k context into VRAM, gpt-oss threads the needle of speed and resource load.
For a model that reliably completes more complicated tasks slowly, a quantized qwen3.8:27b fitting into the profile will work if context length can be constrained to <65k, but it's slow.
More detailed report: https://t.co/9F3aXdZR1Y
Repo with results and code: https://t.co/llFCg1HgrU