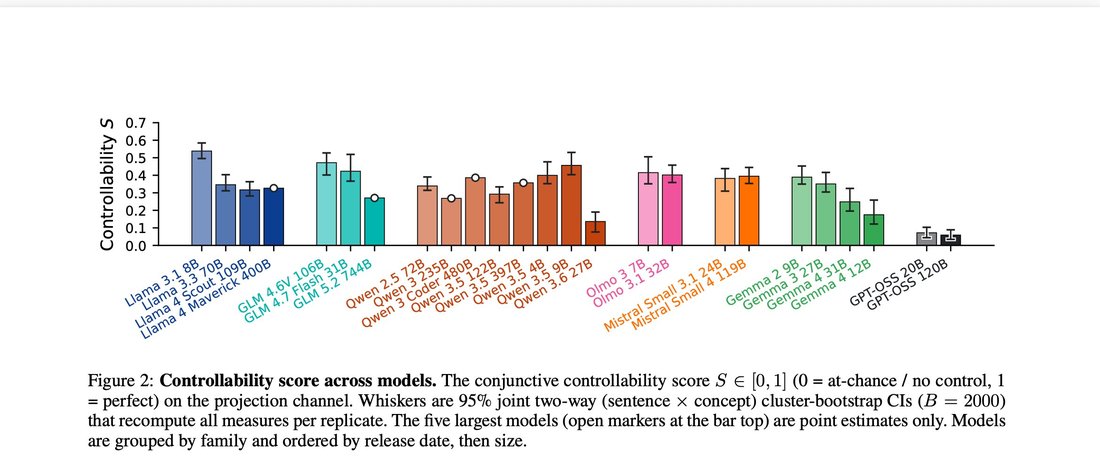
We then combine these measures into a single score, and evaluate a wide variety of open models.
Surprisingly, we find that Llama 3.1 8B Instruct performs best, even over larger and more modern models (such as GLM 5.2, or Llama 4 400B). Both GPT-OSS models were not very good at controlling their activations.
These measurements suggest that activation controllability may be difficult to infer from a model’s size or capability index, and must be measured directly.
Surprisingly, we find that Llama 3.1 8B Instruct performs best, even over larger and more modern models (such as GLM 5.2, or Llama 4 400B). Both GPT-OSS models were not very good at controlling their activations.
These measurements suggest that activation controllability may be difficult to infer from a model’s size or capability index, and must be measured directly.