Qwen3.8-27B running on my RTX 5090, on llama.cpp!
first numbers, Q4_K_M via Unsloth's day-0 GGUF, llama-bench:
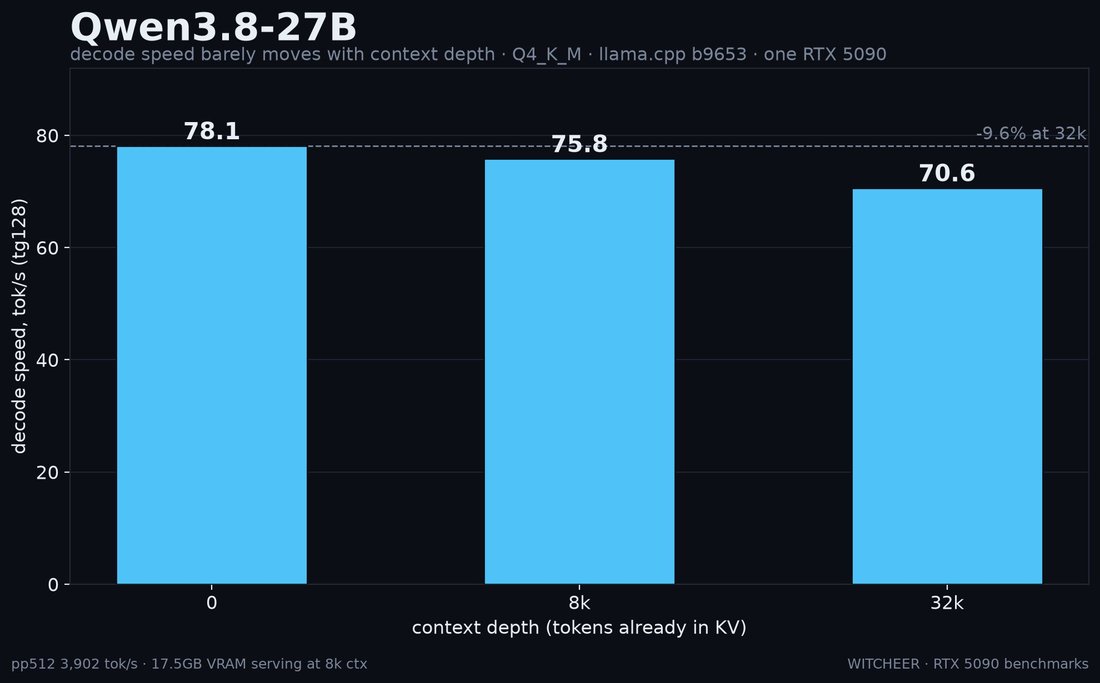
- decode: 78 tok/s empty, 76 at 8k context, 71 at 32k. minus 9.6% at 32k deep
- prompt: 3,900 tok/s (pp512)
- 17.5GB VRAM serving at 8k, so 14GB spare on a 32GB card
quality board runs tonight, full quant ladder after.
first numbers, Q4_K_M via Unsloth's day-0 GGUF, llama-bench:
- decode: 78 tok/s empty, 76 at 8k context, 71 at 32k. minus 9.6% at 32k deep
- prompt: 3,900 tok/s (pp512)
- 17.5GB VRAM serving at 8k, so 14GB spare on a 32GB card
quality board runs tonight, full quant ladder after.